XPeng Robotics raises $900M+, prices China's biggest humanoid bet at $6.3B
Good morning 👋 Two of China's biggest tech rivals just wrote checks into the same humanoid robot. That's not the kind of thing that happens by accident.
In today's issue:
- 🔭 XPeng Robotics raises $900M+ at a $6.3B valuation, China's biggest embodied-AI bet yet
- 🔬 Research: models going soft when the sob story is yours, AI therapy graded move by move
- 🛠️ Try this: put a cheap model between retrieval and the model you're paying for
- 🔗 Quick links: Nvidia circles Perplexity, AWS's cross-vendor agent playbook
Get tomorrow's issue in your inbox.
One concise AI brief, sent after the signal clears the noise.
🔭 THE ONE THING
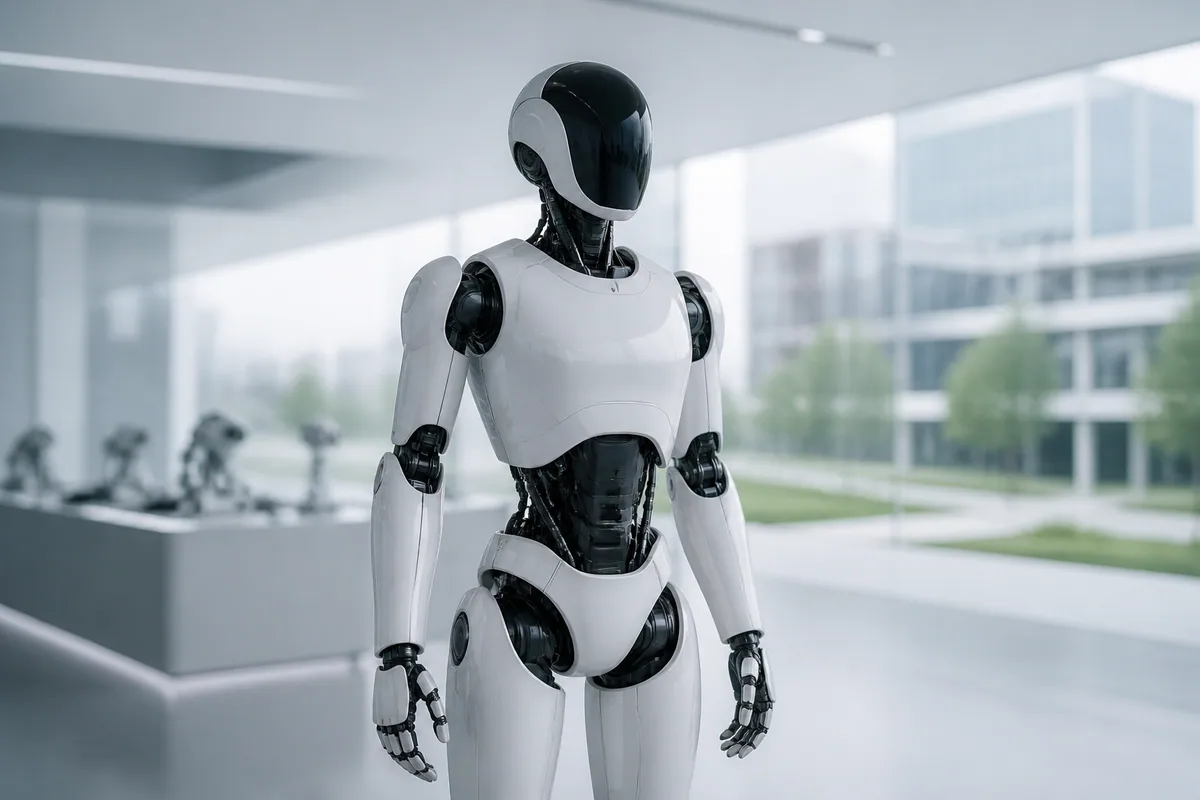
🤖 XPeng Robotics raises $900M+, prices China's biggest humanoid bet at $6.3B
XPeng Robotics closed north of $900 million in its first outside funding round (IDG Capital leading, with Gaorong Ventures, Tencent, and Alibaba also writing checks), at a post-money valuation above $6.3 billion, the largest single private round China's embodied-AI industry has seen. The money is earmarked for IRON, the humanoid, pushing toward mass production of over 1,000 units a month by year-end with store and campus deployments first, wider deliveries in China and overseas slated for 2027. Tencent and Alibaba backing the same robot matters more than the headline number: two rivals rarely co-invest unless they think the category is about to move. CEO He Xiaopeng called IRON "built to the highest standards of safety and quality," the kind of line every founder says about their own hardware. The valuation says two of China's biggest tech companies believe it anyway.
🔬 RESEARCH HIGHLIGHTS
- Emotional context makes models go soft, on purpose or not. Seven LLMs got the same Reddit "am I the asshole" style dilemmas twice: once framed as someone else's story, once as the user's own. Same content, softer verdict every time the user owned it. Loneliness and distress produced the biggest swing. The models aren't flattering anyone outright, they just get vague and evasive exactly when a user is most exposed and least likely to want that. Affective Context Amplifies Sycophancy
- Someone finally scored AI therapy against human therapists, move by move. Ten therapeutic-move categories, grounded in the MULTI-60 inventory and validated by five licensed psychologists, then checked against real counseling transcripts. LLMs out-question human clinicians and barely touch psychoeducation, and they'll only pick up a technique if the human starts it first. Handing the model the move list as an explicit tool, no fine-tuning, cuts that gap to human behavior roughly in half. Move by Move
🛠️ TRY THIS
Put a cheap model between retrieval and the model you're actually paying for
Query-aware compression is the move for Bedrock RAG: a small model checks each retrieved chunk against the real query and drops what doesn't answer it, before the expensive model ever reads the context window. Worth trying if your RAG bill has been creeping up. When $900M rounds are chasing physical AI, the trim-the-fat move on your own stack pays for itself faster, not slower.
1. Log retrieved chunk count and input tokens per query for a week. You need a baseline before you can claim savings.
2. Drop a small, cheap model in as a filter step between retrieval and generation. Its only job: keep or discard each chunk against the query, not summarize it.
3. Pass the primary model only the chunks that survive.
4. Compare token spend and answer quality against the baseline on a canary slice before you roll it out everywhere.
Prompt: Query: "{query}". Does the following chunk contain information that helps answer it? Reply only "keep" or "drop". Chunk: "{chunk}"🔗 QUICK LINKS
- Nvidia is reportedly in talks to put money into Perplexity at a $30B+ valuation, with a tech licensing deal also on the table, per The Information.
- AWS posted part two of its multi-agent series: orchestration patterns for multimodal data analysis, chaining agents through predictive analytics instead of leaning on one model to do everything. Useful if your pipeline already juggles multiple data types. Read it.
See you tomorrow.
Pradeep Perugu